The Hardware Acceleration Dilemma: Why Small Tasks Run Slower
This article provides an in-depth exploration of Hardware, covering foundational concepts, practical applications, and engineering insights.
In the world of modern computing, specialized hardware accelerators like GPUs, TPUs, and specialized chips promise lightning-fast processing speeds. However, developers often encounter a surprising reality: smaller jobs frequently run slower on an accelerator than on a traditional central processing unit (CPU).
If an accelerator is designed for speed, why does this happen? The answer lies in a crucial computational concept known as accelerator overhead.
What Is Accelerator Overhead?
Before a dedicated processor can compute a single calculation, a significant amount of background setup work must take place. This preparatory phase includes initializing the execution environment, allocating memory, launching execution kernels, and physically transferring data from the host system memory to the device across a bus like PCIe.
Once computation finishes, the results must then be copied back to the main memory. This combined sequence of initialization, memory allocation, and data transfer introduces a baseline time penalty. Regardless of whether your task processes ten items or ten million items, this overhead cost remains relatively constant.
The Scale Factor: Why Small Workloads Lose
The economic viability of hardware acceleration depends entirely on the balance between setup overhead and actual processing execution time.
- Large Workloads: When feeding millions of data points into a parallel processing engine, the computational time saved by the accelerator massively outweighs the setup costs. The massive parallel bandwidth easily absorbs the initial data-transfer penalty, yielding a net performance gain.
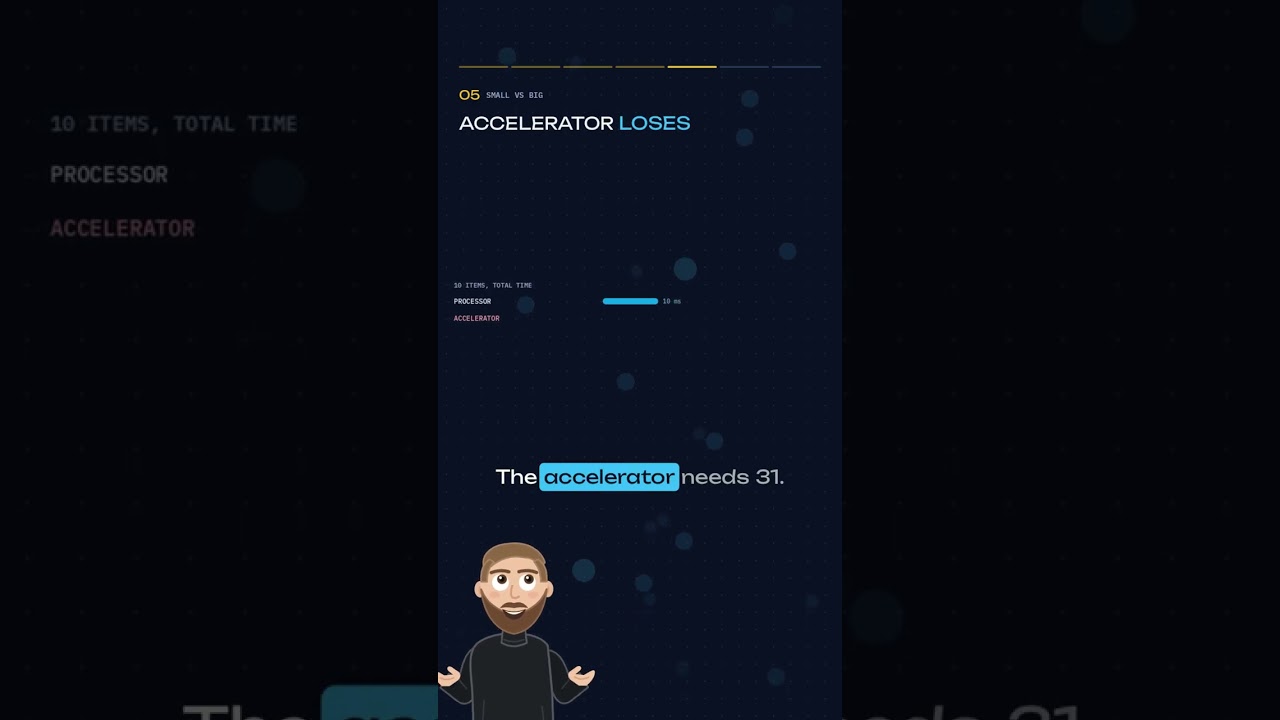
- Small Workloads: When a job is small, the setup and data transfer phases take vastly longer than the actual processing time. A CPU could have finished the entire calculation locally in micro-seconds while the accelerator is still waiting for data to travel across the bus.
In short, specialized chips only deliver speed benefits when there is enough parallel work to amortize the high entry fee of setup latency.
How to Maximize Accelerator Efficiency
To avoid losing performance on smaller workloads, software engineers and data scientists can apply a few key optimization strategies:
- Batch Small Inputs: Group multiple smaller tasks into a single large batch before sending them over to reduce the number of individual transfer calls.
- Keep Data Local: Retain data on the target device across consecutive operations rather than continually sending memory back and forth to the host CPU.
- Benchmark CPU vs. Accelerator: Evaluate task sizes early in development. If the dataset isn't large enough, keeping execution on the primary CPU is often the faster choice.
Understanding the balance between data movement costs and raw compute power allows tech teams to leverage high-performance hardware effectively without falling victim to hidden latency traps.


